How to catch LLM regressions before a model upgrade ships
Sample production logs into a golden set, write deterministic assertions, diff baseline against candidate and gate it in CI. Built on six real failures.
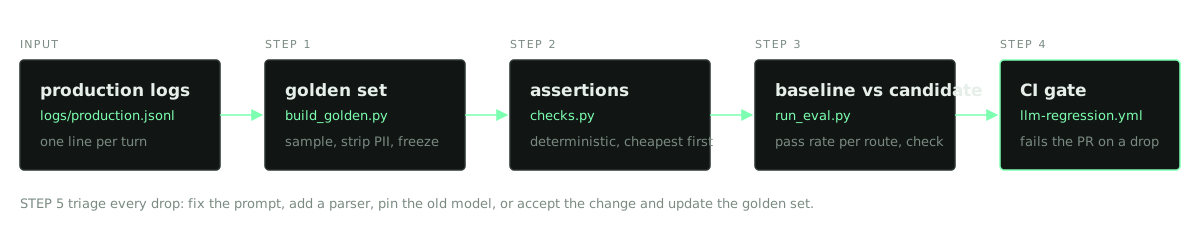
Your provider is retiring the model you run in production, or a cheaper one just shipped and someone has done the arithmetic. Either way, one string in a config file is about to change, and nothing in your test suite has an opinion about what the model says. Here is the process for giving it one: sample real inputs from production into a golden set, write a deterministic assertion for each way an upgrade can break you, run the current model and the candidate over the same cases and diff the pass rates, then put that diff in CI so the next upgrade is a pull request check instead of a week of support tickets.
Everything below runs from one small repo, evalshift/llm-regression-example ↗, and every failure in it is real: it comes from upgrading a three-route agent from Sonnet 5 to Sonnet 5.5. The repo ships the recorded outputs, so the diff runs offline, with no API key.
The reason this needs a process rather than an afternoon in the playground is that the bugs a model upgrade causes are mostly silent. The output still reads fine. A tool argument changed shape, an enum value moved one notch, a ticket landed in a different queue, and nobody sees it until something downstream counts it.
## What actually breaks when you switch models
The agent in the example has three routes: a day planner and a unit converter that call tools, and a ticket triage classifier that returns JSON. Thirty recorded production turns, replayed on both models. Six of the thirty failed a check on the new model that the old one passed, and every one of them produced output a reviewer would have waved through.
| Failure type | What it looked like in our run | How to catch it |
|---|---|---|
| Refusal flips into a hallucinated tool call | "Convert 10 kilometres to kilograms." Sonnet 5 explained the units don't convert. Sonnet 5.5 called convert_units(km → kg) and said nothing. | Pin cases where production answered without a tool, and assert no tool is called. |
| Tool argument drift | "What's on my calendar today?" went from get_schedule(date="2026-09-08") to get_schedule(date="today"), against a prompt rule to resolve relative dates. | A regex on the argument: ^\d{4}-\d{2}-\d{2}$. |
| Extra tool calls | "Any notes about Sam's gift, and when is that task due?" gained a second call, get_tasks, on top of search_notes. Two cases did this. | Compare the set of tools called against the set production called. |
| Schema-valid, wrong value | A double-charge ticket dropped from priority urgent to high. Still valid JSON, still an allowed enum value. | Field equality against the baseline on every enum field. Schema validation alone passes this. |
| Classification shift | A ticket about app logouts and a late refund moved from billing to bug. Different queue, different owner. | Same field-equality check. |
| Format leakage | The old model wrapped its JSON in markdown code fences on 8 of 9 tickets, against an explicit instruction not to. The new one never did. | A strict json.loads on the raw output, separate from the lenient parse your app uses. |
| Verbosity and tone | Suggested replies grew 8% longer and more specific: the new model asks for the Safari version and offers Chrome as a workaround. | Length bounds on fields that have them. A pairwise judge for the rest, advisory only. |
| Latency and cost | Converter latency rose 47%. Triage got 32% faster and 27% cheaper. Planner barely moved. | Mean latency and cost per route, not per run. A single average would have shown a wash. |
The table is from a toy agent, but none of the rows is toy-specific. Every production agent I have looked at has an enum field, a tool argument with a required shape, and a case where the right answer is to not call a tool. The upgrade that gets one of those wrong does not throw.
## Step 1: build a golden set from production logs
The playground fails for a structural reason: the prompts you can think of are the prompts you already handle. The cases that break are the ones a user typed, so the golden set has to come from logs. Log one line per model turn, with everything the assertions will later need:
{"request_id": "planner-000", "ts": "2026-10-12T20:35:51Z", "route": "planner",
 "history": [], "input": "What's on my calendar today?",
 "output": "You have Team standup at 9:30–10:00 AM on Zoom, and a Dentist appointment ...",
 "tool_calls": [{"name": "get_schedule", "args": {"date": "2026-09-08"}}],
 "latency_ms": 1863}
The tool_calls and the output are what production did, and they become the expectations.
Then sample. Aim for 100 to 300 lines, stratified by route or feature, because a 5% regression on
a route that is 5% of traffic is invisible in an unstratified sample. Strip PII before anything
touches disk. Drop repeated inputs: twenty copies of "where is my order" make the suite look twenty
times more certain than it is. And tag the edge cases you already know about, so sampling can
never drop them.
def build(lines: list[dict], per_route: int) -> list[dict]:
    by_route: dict[str, list[dict]] = defaultdict(list)
    seen: set[tuple[str, str]] = set()
    for line in sorted(lines, key=lambda x: x["ts"]):
        key = (line["route"], line["input"].strip().lower())
        if key in seen:
            continue
        seen.add(key)
        by_route[line["route"]].append(line)

    cases = []
    for route, route_lines in sorted(by_route.items()):
        edge = [x for x in route_lines if "edge" in x.get("tags", [])]
        rest = [x for x in route_lines if x not in edge]
        chosen = edge + rest[: max(per_route - len(edge), 0)]
        chosen.sort(key=lambda x: x["ts"])
        for line in chosen:
            cases.append(
                {
                    "id": line["request_id"],
                    "route": route,
                    "history": [
                        {"role": h["role"], "content": strip_pii(h["content"])}
                        for h in line.get("history", [])
                    ],
                    "input": strip_pii(line["input"]),
                    "expect": expectation(line),
                }
            )
return casespython build_golden.py logs/production.jsonl > golden.jsonl
expectation() writes the tools production called with their arguments, or, for the JSON route,
the values of the enum fields. Review the file before committing it, then freeze it. The
expectations say "do what production did", and production is a baseline, not an oracle. If you
are still editing cases while you compare models, you are comparing two moving things.
## Step 2: write assertions, cheapest first
Here is the opinionated part. Every regression in the table above was caught by a check that makes no model call, runs in microseconds, and could be explained to a new hire in one sentence. Embedding similarity scored the priority downgrade at 0.95 and the queue change at 0.87. An LLM judge, asked which output was better, preferred the new model on 8 of 9 tickets, which is true and useless: better prose, wrong priority.
So start with the boring checks, and encode them as data rather than prose:
# Required keys of the triage JSON and their allowed values (None = free text).
JSON_SCHEMA: dict[str, set[str] | None] = {
    "category": {"billing", "bug", "feature_request", "account", "other"},
    "priority": {"low", "medium", "high", "urgent"},
    "sentiment": {"negative", "neutral", "positive"},
    "summary": None,
    "suggested_reply": None,
}
SUMMARY_MAX_WORDS = 20

ISO_DATE = re.compile(r"^\d{4}-\d{2}-\d{2}quot;)
ISO_CURRENCY = {"USD", "EUR", "GBP", "JPY", "CHF"}# What the prompts promise the tools will receive. The model is supposed to
# normalise before calling; these rules say whether it did.
ARG_RULES = {
"get_schedule": {"date": _is_iso_date},
"days_between": {"start_date": _is_iso_date, "end_date": _is_iso_date},
"convert_currency": {
"from_currency": lambda v: v in ISO_CURRENCY,
"to_currency": lambda v: v in ISO_CURRENCY,
},
"convert_units": {"value": _is_number},
}
# Arguments the model phrases freely. A different wording is drift worth
# printing, not a failure.
FREE_TEXT_ARGS = {("search_notes", "query")}Two kinds of check are mixed in here, and it is worth keeping them straight. Baseline checks compare the candidate against what production did: same set of tools, same arguments, same enum values. Contract checks encode what the prompt promises and hold no matter what production did: the JSON parses, the date is ISO, the summary is under twenty words. The baseline checks catch change; the contract checks catch things both models might be getting wrong.
The strict JSON parse deserves its own line. Your app almost certainly strips fences before parsing, because at some point a model added them and someone fixed it in the parser. Keep that parser. But assert on the raw output too, so a model that starts, or stops, adding fences shows up as a change rather than silently depending on a workaround.
Free text gets a judge, and only free text. The suggested reply in a triage ticket has no deterministic contract beyond its length, so a pairwise judge asking "which reply is more specific" is the right tool. Run it advisory, read what it says, and do not let it gate anything until you have audited its calls by hand. Everything above it in this section is the gate.
## Step 3: run baseline against candidate and diff
Run every golden case through both models at temperature 0, apply every check to every output, and compare pass rates per route and per check. Not one average: a run where triage improves and the planner regresses can average out to nothing.
Nondeterminism is real even at temperature 0. The baseline model disagreed with itself on one of
nine tickets between the original capture and the replay: sentiment flipped from negative to
neutral on the same input, same prompt, same model. That is why the runner takes several samples
per case and scores the fraction that pass, rather than one outcome. Three samples per case is
a reasonable default; the pass rate then has a floor you can reason about.
Here is the real output, trimmed to the rows that matter, with one sample per case because that is what the recorded run had:
30 cases, 1 sample(s) each: claude-sonnet-5 -> claude-sonnet-5-5

route      check             n  baseline  candidate   delta
converter  answered          1   100.0%      0.0% -100.0  REGRESSED
converter  arg_format        9   100.0%    100.0%   +0.0
converter  tool_args         9   100.0%    100.0%   +0.0
converter  tool_set         10   100.0%     90.0%  -10.0  REGRESSED
planner    arg_format       11   100.0%     90.9%   -9.1  REGRESSED
planner    tool_args        11   100.0%     90.9%   -9.1  REGRESSED
planner    tool_set         11   100.0%     81.8%  -18.2  REGRESSED
triage     fields            9    88.9%     66.7%  -22.2  REGRESSED
triage     json_schema       9   100.0%    100.0%   +0.0
triage     json_strict       9    11.1%    100.0%  +88.9  improved
triage     summary_length    9   100.0%    100.0%   +0.0

Cases where claude-sonnet-5-5 fails a check claude-sonnet-5 passed:

converter-008  'Convert 10 kilometres to kilograms.'
  tool_set       extra ['convert_units']
  answered       no text reply
  claude-sonnet-5:    "That's not a valid conversion—kilometres measure distance while kilograms measure mass, so there's no meani..."
  claude-sonnet-5-5:  convert_units({"value": 10, "from_unit": "km", "to_unit": "kg"})

planner-000  "What's on my calendar today?"
  tool_args      get_schedule.date: '2026-09-08' -> 'today'
  arg_format     get_schedule.date='today'
  claude-sonnet-5:    get_schedule({"date": "2026-09-08"})
  claude-sonnet-5-5:  get_schedule({"date": "today"})

triage-003  'I was charged twice for my subscription this month and need the duplicate refunded today — this is unacceptable.'
  fields         priority: 'urgent' -> 'high'
  claude-sonnet-5:    '```json {   "category": "billing",   "priority": "urgent",   "sentiment": "negative",   "summary": "Custome...'
  claude-sonnet-5-5:  '{"category":"billing","priority":"high","sentiment":"negative","summary":"Customer was charged twice for th...'

route      metric       claude-sonnet-5 claude-sonnet-5-5   change
converter  latency_ms           1568 ms          2312 ms    +47%
converter  cost_usd             $0.0057          $0.0057     -1%
planner    latency_ms           1481 ms          1538 ms     +4%
triage     latency_ms           3035 ms          2071 ms    -32%
triage     cost_usd             $0.0028          $0.0020    -27%

FAIL: 6 check(s) dropped more than 2% (worst: converter/answered -100.0 points)
The threshold is a policy choice, and it has to respect the denominator. With eleven planner cases, one failure is a nine-point drop, so a two-point threshold means zero tolerance for that route; that is fine as long as you know it. With 300 cases the same threshold tolerates six. Set it per route if the routes differ in how much they matter, and write it down before you look at the numbers, because a threshold chosen after seeing the diff is a negotiation, not a gate.
Look at the n column too. The answered check ran on one case, because production answered
without a tool exactly once in thirty turns. That is a hole in the golden set, not a finding about
the model, and it is the kind of thing this table is for: it tells you which rows you would act
on and which rows you cannot yet trust.
## Step 4: gate it in CI
The run that changes outcomes is the one attached to the pull request that bumps the model string. Trigger it on the files that can move the numbers, and nothing else, because every run spends real money:
name: llm-regression

# Run only when something that can move the numbers changes: the prompts and
# model names (agent.py), the assertions, the golden set, or the runner.
on:
  pull_request:
    paths:
      - agent.py
      - checks.py
      - golden.jsonl
      - run_eval.py
      - .github/workflows/llm-regression.yml
  workflow_dispatch:

permissions:
  contents: read

jobs:
  eval:
    runs-on: ubuntu-latest
    env:
      ANTHROPIC_API_KEY: ${{ secrets.ANTHROPIC_API_KEY }}
    steps:
      - uses: actions/checkout@v7
      - uses: actions/setup-python@v6
        with:
          python-version: "3.12"
      - run: pip install -e .

      # The baseline is the model production runs today. Its outputs only
      # change when the prompt or the golden set changes, so key the cache on
      # those and the candidate is the only side that gets re-run per PR.
      # (This repo commits results/ so it runs offline; in your own repo add
      # results/ to .gitignore and let this cache carry the baseline.)
      - name: Restore cached baseline results
        uses: actions/cache@v4
        with:
          path: results/claude-sonnet-5.jsonl
          key: baseline-claude-sonnet-5-${{ hashFiles('golden.jsonl', 'agent.py') }}

      - name: Baseline vs candidate
        run: python run_eval.py --repeats 1 --max-drop 0.02
The cache is the part people skip. The baseline's outputs only change when the prompt or the golden set changes, so key the cache on those files and the candidate becomes the only side that costs money per pull request. The runner reads a model's results from disk when they exist and only calls the model for what is missing, which is also what lets the example repo run with no key at all.
Ship it in report-only mode for the first week. Let it comment, read what it says, and turn on the failure exit once you agree with it. A gate people learn to re-run until it passes is worse than no gate.
## Step 5: triage what failed
A red check is a list of decisions, and each one has four possible answers: fix the prompt, add an output parser, pin the old model for that route, or accept the change and update the golden set. Walking the six from our run:
- +
get_schedule(date="today"): fix the prompt. The rule was there and the new model weighs it differently; it needs to be louder, and the tool should reject non-ISO dates so the next drift fails loudly. The tool in the original app happened to accept "today", which is exactly why the output looked fine. - +The hallucinated
convert_unitscall: fix the prompt with an explicit "if the request is not a valid conversion, say so without calling a tool", and keep the case pinned. One such case in thirty is too few; add more impossible requests to the golden set. - +The two extra
get_taskscalls: accept. Both questions genuinely span notes and tasks, and the new model is reading them more carefully than the old one did. Update the expected tool set and move on. - +The fences: accept, and keep the strict check. The new model obeys the instruction. The parser stays because the next model may not.
- +
billingtobugon the logout-plus-refund ticket: a judgment call about which queue owns a mixed ticket. Decide, write the rule into the prompt, and the check will enforce it from now on.
The priority downgrade is the one worth a story. The ticket said "charged twice", "refunded today" and "unacceptable". The prompt defines urgent as "the customer is blocked or losing money right now", and whether a duplicate charge counts is a question the prompt never answered, so both models' calls are defensible. The decision took two minutes: a disputed charge is urgent, say so in the prompt, keep the field check. Without the diff, that two-minute decision would have been made by the model, silently, for every double-charge ticket after the upgrade, and the first sign would have been an SLA report a month later.
## Doing this with EvalShift
Disclosure: I'm the founder of EvalShift, and the three scripts above are the method it
automates. The capture SDK replaces the log exporter, evalshift.yaml replaces checks.py, and
the run comes back with paired statistics and a policy verdict instead of a pass-rate threshold.
from evalshift import capture

@capture.agent(suite="triage", redact=True)   # no-op unless EVALSHIFT_CAPTURE=1
def handle_ticket(message): ...
pip install evalshift
evalshift capture sync      # recorded runs -> golden suite
evalshift compare           # baseline vs candidate -> report.html + verdict
- uses: evalshift/evalshift-action@v0
  with:
    token: ${{ secrets.EVALSHIFT_TOKEN }}
    fail-on: policy
The checks in this post map onto its evaluators one to one: tool_selection is the tool_set
check, tool_arguments is tool_args, and the ARG_RULES table is a trace_invariants block
in YAML, with the same ISO-date regex. The example repo ships that file too. What you get on top is
the part that is tedious to write yourself: Wilson intervals on every rate so a small suite returns
inconclusive instead of a false fail, per-slice budgets, and a single-file report with the
per-example diff. The reports behind this post were EvalShift runs; the scripts reproduce them
from the recorded outputs. Docs: /docs/golden-suite,
/docs/evaluators, /docs/action. Side-by-side comparisons
with Promptfoo, DeepEval, LangSmith and Langfuse are at /compare.
## FAQ
How many test cases do I need? Enough that every route you would act on has about twenty, after de-duplication. Thirty total was enough to show every failure type here and not enough to make a decision on any single route. One hundred to three hundred, stratified by route, is the range where pass-rate deltas start meaning something.
Can I use an LLM as a judge? For free-text fields, yes, and only after the deterministic checks have had their turn. In our run the judge preferred the new model on 8 of 9 tickets while the priority field regressed. Keep judge results advisory until you have audited the pairs it got wrong.
How do I handle nondeterministic outputs? Temperature 0, several samples per case, and pass fractions instead of single outcomes. The baseline model here changed a sentiment label between two runs of the same input. One sample per case cannot distinguish that from a regression; three can.
How often should I re-run the tests? On every change to the prompt, the model string, the
tool definitions or the golden set, which is what the workflow's paths filter encodes. Not on
every commit: the run costs money and nothing else can move the numbers.
Should I change the prompt in the same pull request as the model? No. Run the new model on the old prompt first so the diff isolates the model. Then tune the prompt in its own pull request against the same frozen cases. Two variables in one comparison leave nobody able to say which one moved the score.
## Keep reading
- +What actually breaks when you switch LLMs — the longer argument for why the worst regressions read as correct.
- +Build a golden eval suite from production traffic — the capture-first version of step one.
- +LLM regression testing in CI — the pull request gate with the GitHub Action, including the calibration week.
- +When to trust an LLM judge — what pairwise judging is good at, and where it quietly misleads you.